bitHuman
Real-time AI avatars that run on the device — in your app, in your building, or in our cloud.
EnterpriseDocs
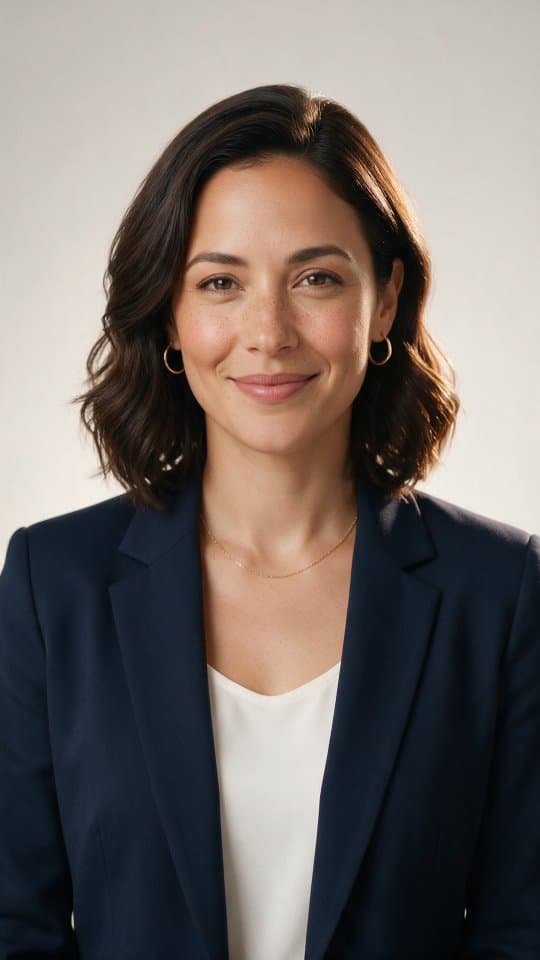
A photoreal person from one portrait.
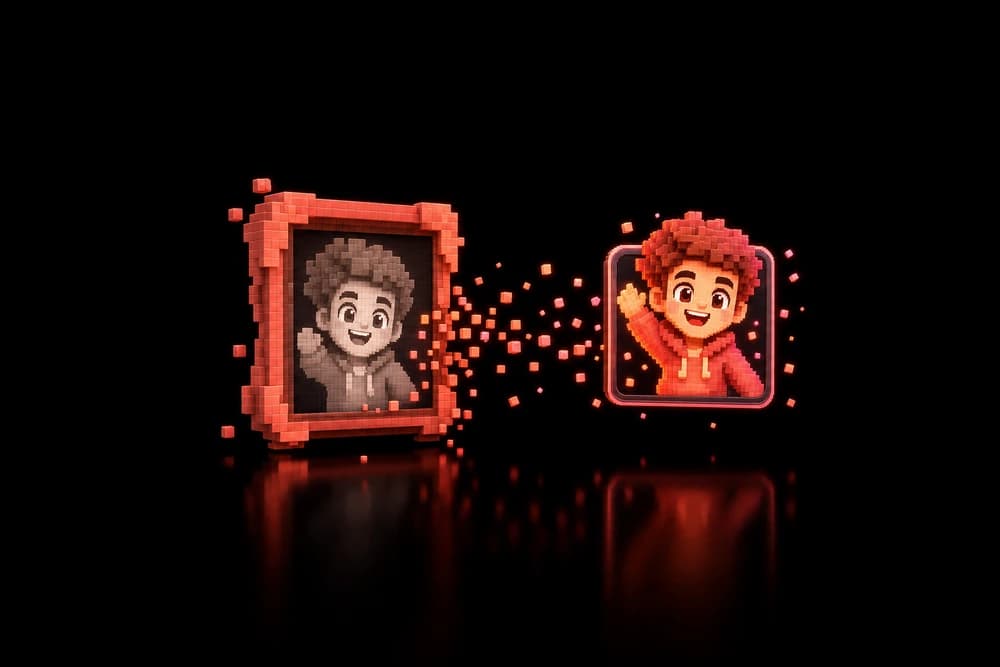
Any character, animated from one image.
How the models work →